
You ask your AI assistant a simple question about your Amazon campaigns. Which keywords had the worst ROAS last week? The answer comes back quickly, formatted cleanly, sounding completely authoritative.
The number is wrong. Not obviously wrong in the way a crashed program is wrong: there is no error message, no red warning, no indication that anything failed. It is the kind of wrong that only becomes visible when you check the same number in Seller Central and find a different figure entirely.
This is what an Amazon MCP hallucination looks like. And it happens, not because the AI is broken, but because the instructions it was given to use the tool had a gap, and it filled that gap the only way it knows how: by drawing on everything it learned during training and making a confident-sounding inference.
Understanding why this happens, specifically the empty parameter schema problem, is the difference between trusting MCP outputs that deserve trust and catching ones that silently got something wrong.
What a Parameter Schema Is and Why It Matters to an AI
The Instruction Manual the LLM Reads Before Acting
When an AI tool like Claude or ChatGPT is connected to Amazon MCP, it sees not just the tools available but a schema for each tool: a structured specification that describes what the tool does, what inputs it needs, what values those inputs can take, and what the output will look like.
Think of it as the instruction manual the AI reads before it tries to use a tool. A well-written manual tells the AI: this tool takes a campaign ID (must be a string in this format), a date range (must be in ISO 8601), and an attribution window (must be one of these five specific values). The output will contain these fields with these meanings.
Incomplete schema information can increase reliance on other available context and model inference, which can increase the risk of an incorrect tool call or interpretation.
What an Empty Schema Actually Looks Like
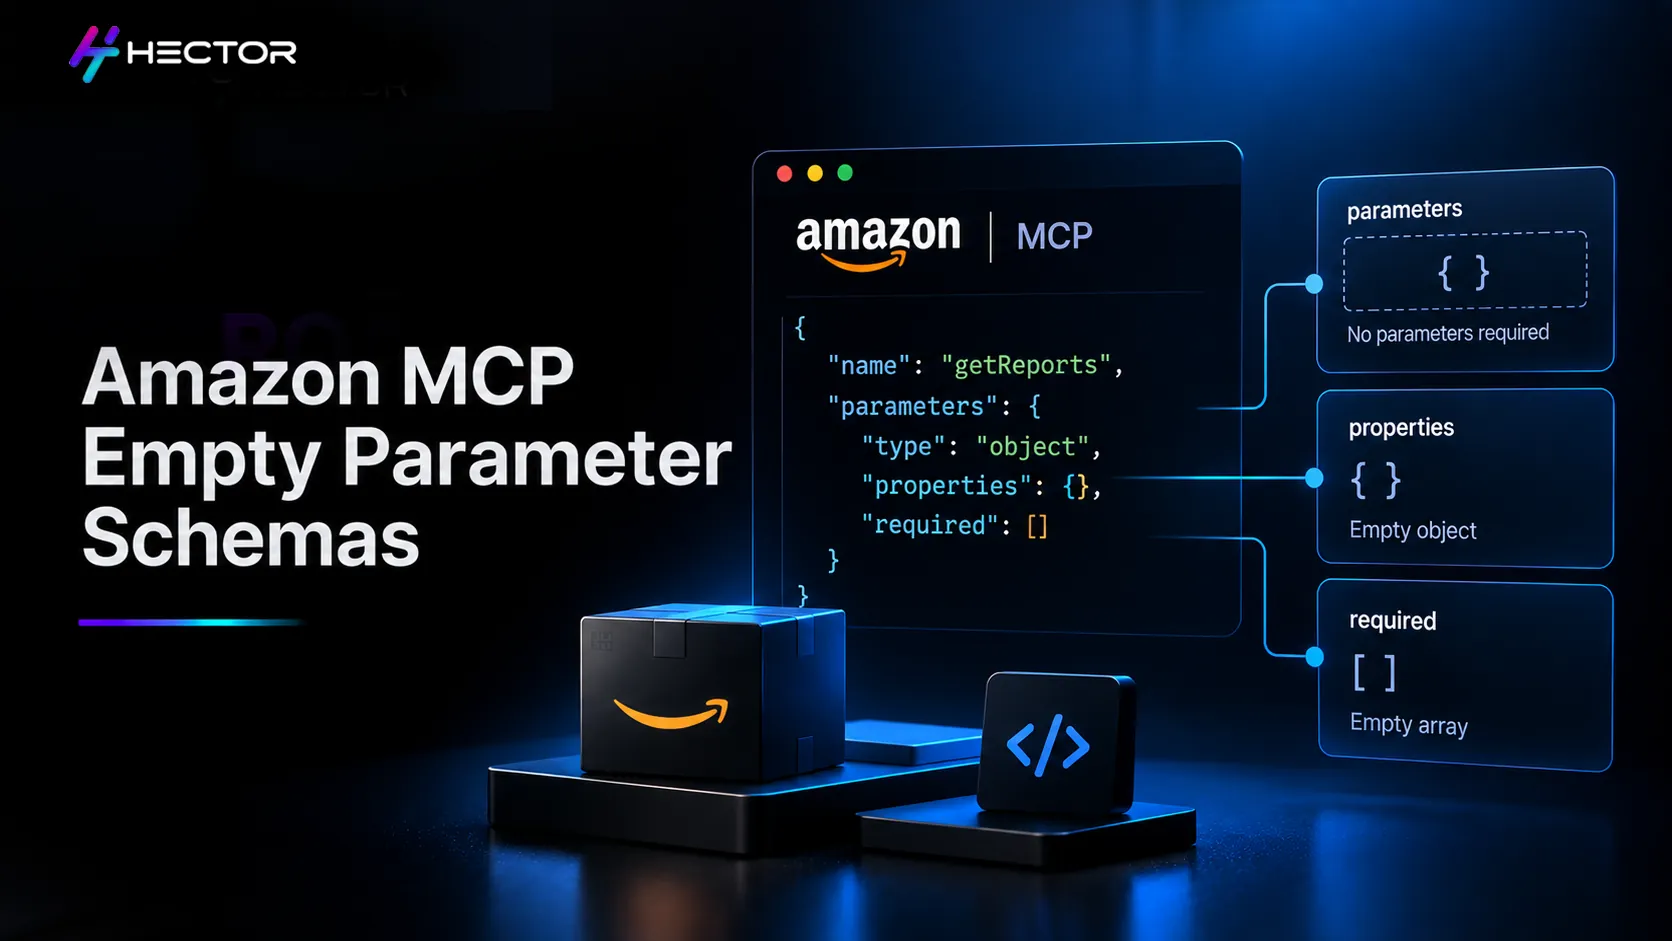
In the MCP protocol, every tool comes with an inputSchema: a JSON object that formally specifies what parameters the tool accepts. A complete schema lists the parameter names, their types, whether they are required, what valid values they can take, and ideally a plain-language description of each one.
An empty schema looks like this:
An inputSchema with no defined properties can be valid for a tool that requires no parameters. If a tool does require parameters but its schema does not adequately describe them, that can create ambiguity for the model.
The Hallucination Mechanism: How the LLM Fills in What It Was Not Told
Gap-Filling From Training Data
An LLM's response to an incomplete schema depends on the model, MCP client, tool description, surrounding context, and available validation. It may infer parameters, request clarification, or generate an invalid tool call that returns an error.
For a tool called get_campaign_performance, the LLM draws on its training data about Amazon advertising APIs, its general knowledge of advertising metric names, its understanding of common date range formats, and its familiarity with similar tools it encountered in training. From all of that, it constructs a plausible-seeming tool call.
Sometimes the inference is right. When a domain is well-represented in training data and the conventions are broadly consistent, gap-filling produces reasonable outputs. The risk is specifically when the domain has precise, non-obvious rules that general training data does not reliably encode.
Amazon advertising is exactly that domain. Amazon Ads defines ACoS as ad spend divided by ad-attributed sales, expressed as a percentage. ROAS is the inverse relationship, calculated as ad-attributed sales divided by advertising spend. Attribution windows have specific names and lengths that vary by ad type. Amazon Ads targeting capabilities and documentation can change over time, so current Amazon documentation should be used when interpreting match types and targeting behavior. These details are not universally consistent in the text the AI was trained on.
Confident Wrong: The Most Dangerous Failure Mode
Here is the part that makes empty schemas genuinely dangerous rather than just inconvenient. When an LLM makes an inference based on a documentation gap, it does not signal that it made an inference. It answers with the same confident tone, the same clean formatting, the same authoritative-sounding language it would use if the answer were verified and certain.
Think of a server who confidently tells you the fish special is salmon when they actually have no idea what fish was used today and have just made an assumption based on what the restaurant usually serves. The words sound definitive. The smile is assured. The dish that arrives might be something else entirely.
An LLM producing a hallucinated answer from an empty schema gives you the same output format as a correct answer. The same number of decimal places. The same field names. The same tone. You cannot tell from the response alone whether it came from actual data or from a confident inference that happened to be wrong.
The Specific Problem With Amazon MCP's Own Schema Design
Tools-Only With Thin Documentation
Amazon Ads MCP Server exposes Amazon Ads capabilities through the MCP framework. Amazon's current documentation describes the Amazon Ads layer as exposing features and data through tools, resources, and prompts. This architectural choice has implications beyond the async reporting issue it is more commonly discussed for.
Schema completeness can vary across MCP implementations. If specific Amazon Ads MCP tools expose incomplete parameter descriptions, that could increase ambiguity for an AI agent. Any such examples should reference the actual current tool schema.
Amazon's MCP Server is not uniquely problematic: the MCP ecosystem broadly has a schema quality issue. But Amazon advertising is a domain where the consequences of schema gaps are particularly significant, because the metrics and conventions are specific and the decisions made on them (bid changes, campaign pauses, budget reallocations) have real financial consequences.
What the LLM Guesses When Amazon's Tool Gives It No Constraints
When an Amazon MCP tool has an empty or thin parameter schema, the LLM doing the tool call has to make a set of assumptions. The most significant ones for advertisers:
What attribution window to use for conversion data: click-through only? View-through? How many days? Amazon's attribution options are specific, and the correct choice depends on ad type and business context.
Which sales metric and attribution methodology to use when interpreting ROAS? Amazon Ads ROAS is calculated using ad-attributed sales divided by advertising spend.
Which campaigns, ad groups, or keywords to include in a query: whether to pull all, active only, or a specific subset that the user did not specify.
How to handle a date range that doesn't match Amazon's reporting windows: whether to truncate, extend, or return an error.
None of these are outlandish guess. They are reasonable inferences from a well-trained model. But reasonable is not the same as correct, and a systematically wrong assumption about attribution windows or ROAS definition will produce results that look right and are materially inaccurate.
What Amazon Advertising Hallucinations Actually Look Like
ROAS Calculated With the Wrong Denominator
Amazon Ads ROAS is calculated as ad-attributed sales divided by advertising spend. Advertisers may build their own business metrics using total revenue, organic revenue, margins, or other inputs, but those should not be presented as the standard Amazon Ads ROAS metric. Amazon defines ROAS and ACoS in its current reporting documentation. AI-generated analysis should use the metric definitions applicable to the specific Amazon Ads report being analyzed.
An LLM filling in the ROAS definition gap from its training data may use the general definition rather than Amazon's current specific one. The formula structure looks right. The field names look right. The number it produces differs from what Seller Central shows. And unless you cross-check, you would not know which one is correct.
Attribution Windows Misapplied
Attribution windows can differ by ad product, advertiser type, and reporting metric. For example, current Amazon reporting documentation standardizes Sponsored Brands and Sponsored Display applicable metrics around a 14-day attribution window, while Sponsored Products attribution can differ between sellers and vendors. A Sponsored Display campaign and a Sponsored Products campaign in the same account use different windows to attribute the same conversion event.
An AI agent could select or interpret the wrong reporting metric or attribution field if the available instructions are unclear. However, Amazon's reporting APIs define the supported attribution metrics and windows. The model does not independently change Amazon's underlying attribution methodology. The conversion count will differ. The ROAS and ACoS calculations will differ. The campaign appears to perform differently than it actually does, and a bid decision is made from that data on a false premise.
Match Types and Targeting Assumptions Filled In From General Knowledge
Amazon's match type behaviour, specifically what broad match actually matches in 2026 versus what it matched in 2022, is documented in Amazon's own help resources, but is a relatively niche piece of knowledge that changes periodically. LLM training data captures these specifics at a point in time and with varying accuracy.
When an LLM is asked to analyse search term performance and fill in assumptions about expected match type behaviour, it may apply outdated or platform-generalised rules. A search term analysis that concludes "this broad match keyword is performing as expected" may be drawing on a definition of broad match that no longer applies.
The Silent Failure Problem: Why You Cannot Tell It Happened
No Error, No Warning, Just a Polished Wrong Answer
The reason empty schema hallucinations are particularly difficult to manage is that they produce no signal of failure. An API error tells you something went wrong. A tool called that returns an explicit error message tells you what was wrong. A hallucinated answer produced from an empty schema gives you a well-formatted, grammatically correct, confidently stated response that is simply inaccurate.
This is the kitchen error you only discover when the dish arrives. The waiter took your order correctly. The kitchen made something different because the instructions were ambiguous. The dish is presented beautifully. You eat several bites before realising it is not what you ordered. Nothing in the presentation told you something had gone wrong.
The Empty Search Result That Looks Like 'No Data'
There is a related failure mode that is equally insidious. When an MCP tool call sends incorrect parameters, perhaps because the LLM used a wrong field name based on a schema gap, Incorrect parameters can produce errors or unexpected results depending on the API operation. An empty result should therefore be validated before concluding that no matching advertising data exists.
The tool returns zero results. The LLM receives the empty response. Rather than flagging an error, it reasons around the emptiness: "No campaigns matched the criteria. This might be because your date range has no data." The explanation sounds plausible. The actual cause is that the tool call had a wrong parameter and Amazon returned empty rather than an error. You acted on a false 'no data' signal.
Four Safeguards That Reduce the Risk
1. Verify Critical Outputs Against Seller Central Directly
For any MCP-derived performance number that will drive a real decision: a bid change, a budget reallocation, a campaign pause, check the same metric in Seller Central's own reporting interface before acting. This sounds obvious, but it is easy to skip when an AI response arrives formatted cleanly and authoritatively.
The time cost of a spot-check is much lower than the cost of a campaign decision made on a hallucinated metric. Verification is not distrust of the AI: it is recognition that the AI is working from schema instructions that may have gaps it cannot compensate for perfectly.
2. Ask the AI to Show Its Working
One of the most effective safeguards against silent hallucination is to ask the AI to explain how it arrived at a number before you use it. "What attribution window did you use for that ROAS figure?" "Which revenue definition did you apply?" "What date range did the report actually pull?"
Asking the AI to state the parameters, metric definitions, date range, and attribution fields it used can help surface potential inconsistencies. Still, the explanation itself should not be treated as proof that the underlying tool call was correct. When the assumptions are visible, you can evaluate whether they match your account's conventions. A hallucinated assumption is much easier to catch when the AI has been asked to state it plainly rather than embed it silently in a confident-sounding conclusion.
3. Use a Structured Data Layer With Pre-Defined Business Logic
The root cause of schema-gap hallucinations is that the LLM has to infer business logic that should have been specified. A structured analytics layer with predefined metric definitions and business logic can reduce the amount of interpretation required from the LLM and lower the risk of inconsistent calculations.
When the AI queries a structured system with clearly defined metrics and business logic, the risk of schema-related ambiguity is reduced because less metric interpretation is left to the model. The AI receives a number labelled precisely as "ROAS (7-day click attribution, Sponsored Products, ad-attributed revenue only)" rather than a raw figure it must attribute and interpret itself. Platforms like Hector Ai are built around this architecture for exactly this reason: the business logic should be defined once in the data layer, not re-inferred every time by a model working from potentially thin schema documentation. Amazon Marketing Cloud provides the clean-room data environment where metric definitions and attribution logic can be standardised across campaigns.
4. Treat MCP Analytical Outputs as Drafts
The most practical general safeguard is to change how you use MCP analytical outputs in your workflow. Use them as a starting point for investigation, not as a final answer that triggers action. An AI summary of campaign performance is useful for identifying what to look at. It is not a reliable substitute for a verified report when the action in question has real financial consequences.
MCP is powerful for execution: creating, pausing, adjusting, where the action is structural, and its correctness is verifiable immediately. For analytical conclusions about performance, treating the AI output as a draft that you verify before acting substantially reduces the risk of a confidently wrong number producing a wrong decision.